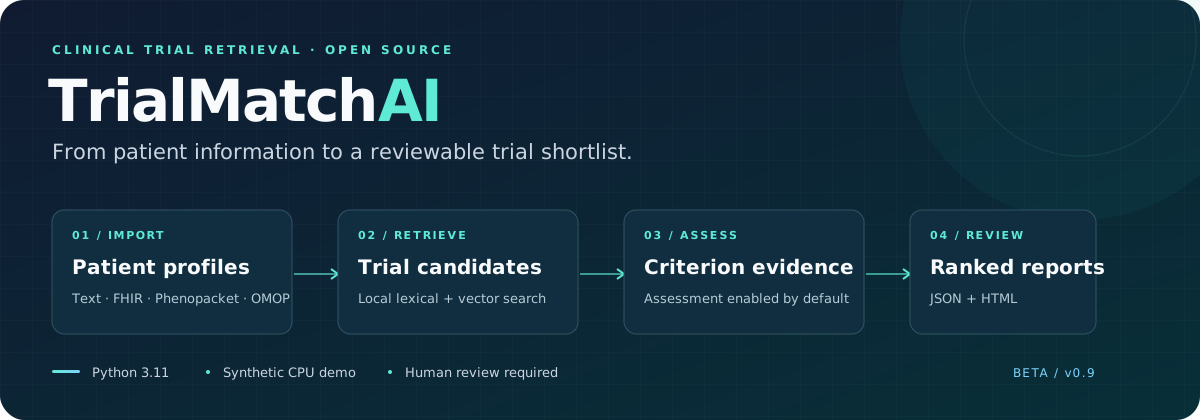
A configurable CLI for patient-to-trial retrieval and eligibility review.


Try the demo · Run your own data · Reproduce the paper · Architecture · CLI · Development
TrialMatchAI imports patient information, searches a local clinical-trial index, and produces ranked results and portable HTML reports. Configured local models perform biomedical entity extraction, reranking, and criterion-level eligibility assessment. Query expansion can be enabled separately.
Release status: beta. The automated release gates exercise the installed CLI with synthetic data and real CPU search. They do not qualify GPU inference, clinical accuracy, or a production clinical deployment. Trial recommendations and generated explanations require qualified human review; a high retrieval score does not establish eligibility.
Use Python 3.11. The base installation includes the CLI and embedded search; it does not install the optional model stack.
python3.11 -m venv .venv
source .venv/bin/activate
python -m pip install trialmatchai==0.9.1

trialmatchai --version
trialmatchai demo --workdir ./demo-workspace
trialmatchai demo --workdir ./demo-workspace --resume
Open the printed results/demo-patient/report.html path in a browser. Choose an
empty directory for the first run. The demo creates three synthetic trials and a
synthetic FHIR patient, prepares a real LanceDB index, filters and ranks candidates,
and renders a report. It uses BM25 and deterministic hashing embeddings; model
inference and model downloads are disabled.
Resume preserves completed ranking results and repairs a missing or truncated patient report. Demo inputs and configuration are checksummed: use a new workspace for a different configuration. This is a software walkthrough, not a clinical benchmark.
| Area | Implemented today | Qualification boundary |
|---|---|---|
| Patient input | Text, FHIR, Phenopacket, and OMOP importers; canonical profiles and summaries | Format coverage is partial; validate mappings against your source data |
| Retrieval | Local LanceDB tables, BM25/vector/hybrid search, multi-channel fusion, structured filters | Retrieval quality depends on corpus, embeddings, filters, and candidate budgets |
| Model stages | Entity extraction, default-on reranking and eligibility assessment, optional query expansion | Requires extra dependencies, model access, and runtime qualification |
| Review | Ranked JSON, per-trial outputs, individual and multi-patient HTML reports | No hosted clinical workspace, authentication, review queue, or sign-off system |
| Operations | CLI stages, registry updater, checksum tools, synthetic e2e, verified package publishing | Complete cache invalidation, GPU qualification, and application deployment remain open |
| Agent behavior | A fixed sequence of configurable stages, with optional LLM expansion | Bounded retrieval/review agents are planned; autonomous task planning is not implemented |
The codebase review records the audit findings. The production roadmap turns them into sequenced work across ranking quality, clinical workflow, agents, and delivery.
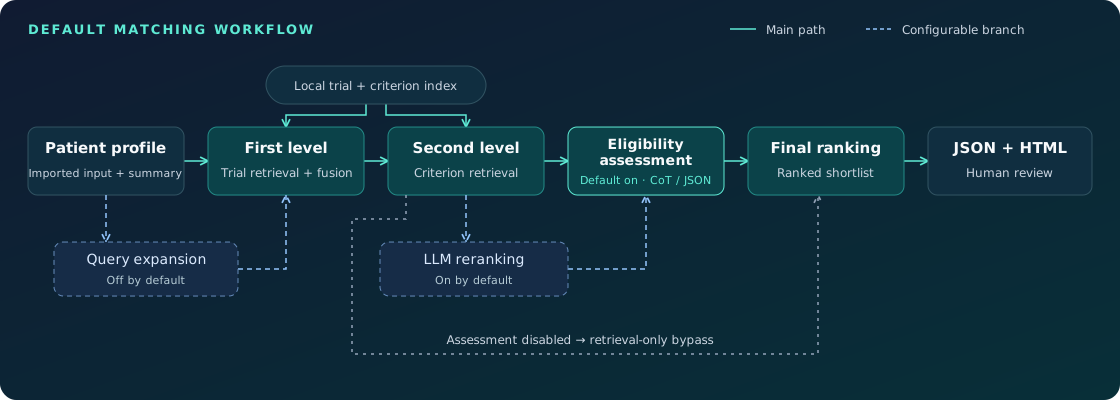
The build path prepares trial records and criterion rows, then indexes them. During matching, first-level retrieval gathers trial candidates across query channels; second-level retrieval selects criterion evidence. Reranking, constraint scoring, and default-on eligibility assessment contribute to the final output. The code calls its generated eligibility explanations CoT reasoning; these are model outputs to inspect alongside source evidence, not verified clinical reasoning or a guarantee that every criterion has been covered.
Starting with 0.9.1, eligibility assessment and CoT prompt style have independent switches:
rag.enabled |
use_cot_reasoning |
Result |
|---|---|---|
true (default) |
true (default) |
Eligibility assessment using the CoT prompt |
true |
false |
Eligibility assessment using the direct JSON prompt |
false |
Either | Retrieval-only ranking; no eligibility assessment |
Both assessment prompts request criterion classifications and evidence-based
justifications. rag.no_think separately controls supported models' thinking-mode
settings. Rankings record their mode and assessment availability; reports label
retrieval-only results and suppress assessments left over from earlier runs.
Missing or unusable assessment outputs are not an eligibility verdict.
Migration from 0.9.0: to disable assessment, explicitly set rag.enabled: false.
Setting only use_cot_reasoning: false now keeps assessment enabled. Legacy matches
without the new mode metadata are recomputed when matching resumes; changing the
assessment switches or rag.max_trials_rag also invalidates their cached results.
Incomplete assessments remain pending on resume, reusing compatible successful
trial outputs and retrying missing or unusable ones. Aborted attempts cannot reuse
verdicts from a prior configuration. This does not establish
complete patient/model/corpus cache identity, which remains roadmap work.
The default configuration selects BAAI/bge-m3 embeddings,
fastino/gliner2-base-v1 entity extraction, google/gemma-2-2b-it reranking, and
microsoft/phi-4 eligibility reasoning with TrialMatchAI adapters. Query expansion
is disabled by default. See the actual defaults
and pipeline guide for stage controls and configuration.
The declared runtime is Python 3.11. CI verifies Linux CPU execution. Model memory, CUDA compatibility, and throughput must be established for the configuration and hardware you select; there is no universal single-GPU capacity promise.
| Installation | Intended use |
|---|---|
trialmatchai |
CLI, synthetic CPU demo, import/report/artifact utilities |
trialmatchai[entity] |
GLiNER2 entity extraction and its model dependencies |
trialmatchai[llm] |
Embedding and language-model dependencies |
trialmatchai[llm,gpu,entity] |
Optional full model stack on a compatible Linux CUDA host |
trialmatchai[finetune] |
Training dependencies; see the fine-tuning guide |
For the default model pipeline, install its extras in a dedicated environment:
python -m pip install 'trialmatchai[llm,gpu,entity]==0.9.1'The optional inference stack has unresolved dependency advisories and has not passed full GPU load/inference qualification in this release. Review the validation record before deploying it.
Export the packaged configuration into your workspace:
python - <<'PY'
from importlib.resources import files
from pathlib import Path
Path("config.json").write_text(
    files("trialmatchai").joinpath("config/config.json").read_text(encoding="utf-8"),
    encoding="utf-8",
)
PY
Edit the model, data, output, and device settings for your installation. For adapters, supply downloaded local directories: the current path normalizer treats Hub adapter IDs as local paths, an open P09 compatibility issue. The configuration schema and environment example describe overrides. Obtain access to any gated models before running the pipeline. Model and vocabulary downloads, registry refreshes, and access checks can use the network; deploying locally does not by itself establish an offline or compliant environment.
Use normalized trial JSON under data/trials_jsons/, then prepare and index it:
trialmatchai build --config config.json
trialmatchai build --config config.json --status
Alternatively, bootstrap-data downloads the configured prepared corpus archives.
For verified downloads, obtain their expected digests through a trusted channel:
trialmatchai bootstrap-data --root . --checksum-manifest /path/to/trusted/SHA256SUMS
trialmatchai index --config config.json
The manifest path above is a placeholder for your trusted corpus manifest; package-release checksums do not authenticate separately hosted corpus archives. Bootstrap without digests remains supported for legacy sources and warns that verification is unavailable. Use compatible embedding settings when indexing precomputed vectors.
Concept linking is optional. trialmatchai build --config config.json --concepts
builds the open-vocabulary concept store; licensed OMOP vocabulary files can be
supplied separately. See pipeline guide.
trialmatchai e2e --config config.json --input patient.fhir.json --format fhir
trialmatchai report --config config.json --patient YOUR_PATIENT_ID
trialmatchai report --config config.json --all
Replace YOUR_PATIENT_ID with the imported profile ID. Text notes, Phenopacket JSON,
and OMOP extract directories are also accepted by the importer. FHIR resources
with explicit unresolved patient references are rejected in strict mode or kept
as unsupported input in lenient mode; they are not silently assigned to the sole
patient. Consult the interoperability guide for supported
fields and validation behavior.
With default paths, the workspace contains:
data/
├── trials_jsons/          # normalized registry records
├── processed_trials/     # prepared trial records
├── processed_criteria/   # prepared eligibility criteria
├── search/               # embedded LanceDB search tables
└── patients/             # raw copies, canonical profiles, summaries
results/
├── <patient-id>/
│   ├── ranked_trials.json
│   └── report.html
└── index.html            # multi-patient report
Reports can contain patient information. Configure access, retention, and sharing for your environment. The repository does not provide these organizational controls.
Run trialmatchai <command> --help for the current options.
| Command | Purpose |
|---|---|
demo |
Exercise synthetic import, CPU search, reporting, and resume |
pipeline |
Select stages with --only, --from, --to, --skip, and --force |
build / index |
Prepare the corpus and build search tables / index prepared data |
build-concepts |
Build the optional concept-linking store |
bootstrap-data |
Download and extract prepared data and optional model/training archives |
import-patient |
Create canonical patient profiles and summaries |
e2e / run |
Import and match / match staged profiles |
report |
Render a patient report or the multi-patient front page |
update-registry |
Fetch and upsert ClinicalTrials.gov studies; optional watch mode |
trec |
Run TREC Clinical Trials evaluation presets |
trec-evaluate |
Re-score completed TREC rankings with explicit unjudged policies; no GPU inference |
reproduce-paper |
Verify and recalculate the published TREC 2021/2022 result artifact |
finetune |
Train supported reasoning, reranker, or NER components |
healthcheck |
Inspect configured dependencies, paths, and services |
artifacts |
Create or verify portable SHA-256 manifests |
Resume is stage-specific. Completion files do not yet fingerprint every input, configuration, and model revision. After changing these, explicitly rebuild or force the affected stages; successful resume alone does not prove data freshness. Registry synchronization and deletion/status propagation also need qualification before use as a live trial directory.
trialmatchai artifacts manifest ./artifacts --json
trialmatchai artifacts verify ./artifacts/SHA256SUMS --require-exact --json
Verification rejects missing/corrupt files, unsafe paths, and symlinks; exact mode also rejects unexpected files. Trusted bootstrap digests bind the downloaded archives to completion markers. Corrupt caches are quarantined with a bounded retry. Changed archives extract into fresh trees, with previous trees retained as backups and unrelated model directories preserved.
Bootstrap serializes writers and recovers interrupted publication on the next run. Replacement uses two directory renames, so stop consumers during updates. Resume checks marker provenance and managed roots; it does not rehash all extracted files. Backups and quarantine files consume disk until reviewed and removed. See the delivery runbook for the exact guarantees and legacy migration.
trialmatchai trec --tracks "21 22" and --tracks "23" expose the benchmark
presets. Reproducible comparisons require fixed corpus snapshots, topics, qrels,
model revisions, configuration, and a stated treatment of unjudged trials.
The current evaluator and retrieval pipeline have open audit findings; this
release does not claim a newly measured ranking improvement or a validated
comparison against another system.
Completed rankings can be evaluated without repeating retrieval or model
inference. trialmatchai trec-evaluate reports both condensed metrics that
exclude unjudged trials and metrics that retain unjudged trials with gain zero.
See the TREC evaluation guide
for commands, input fingerprints, and measured policy sensitivity across the
existing complete runs.
The published TREC result artifact can be audited on CPU with one command:
trialmatchai reproduce-paper --workdir ./paper-reproductionThis verifies the pinned Zenodo archive, aggregates its stored per-topic metrics, recalculates metrics from the archived rankings, and evaluates the same rankings with the current metric implementation. It does not rerun model inference. The archived summaries are internally consistent, but some archived rankings do not regenerate their stored topic metrics, and the present tie-aware evaluator is not the evaluator used for the paper values. See the full reproduction record for the measured differences, retrieval recall, offline usage, and the inputs still required for an exact historical rerun.
The research paper describes the published study. Its results should be distinguished from this release's software checks. The roadmap prioritizes retrieval recall, eligibility semantics, evidence coverage, benchmark integrity, and a usable review workflow before bounded agent experiments.
git clone https://github.com/cbib/TrialMatchAI.git
cd TrialMatchAI
uv sync --frozen                 # CI uses uv 0.11.24 and Python 3.11
make lint
make test
make demo
make release-check              # full local package/CLI/security rehearsal
CI and release publishing use the same verification workflow: frozen dependency resolution, lint, workflow validation, tests, secret/dependency scanning, optional CPU model imports, package construction, and an isolated installed-wheel CLI e2e. The smoke checks real indexing, filtering, ranking, HTML, report repair, resume, and checksum commands with model downloads disabled.
Release tags must match package and module versions. Publishing verifies the tested wheel and sdist against SHA-256 digests, records build inputs, attaches provenance, and uses PyPI trusted publishing without rebuilding. These are package delivery gates; production application deployment, GPU integration tests, complete optional stack auditing, and clinical acceptance gates remain roadmap work.
Use the release runbook, validation evidence, security policy when preparing changes. Report reproducible bugs through GitHub issues; do not include identifiable patient data or credentials.
Abdallah, M. et al. TrialMatchAI: an end-to-end AI-powered clinical trial recommendation system to streamline patient-to-trial matching. Nature Communications 17, 4472 (2026). Read the paper and citation.
TrialMatchAI code is distributed under the MIT license. Datasets, model weights, and clinical vocabularies have their own terms.