Repository navigation
refactor: use group clustering terminology in aggregate execution - #24697
Conversation


Codecov Report❌ Patch coverage is Additional details and impacted files@@ Coverage Diff @@
## main #24697 +/- ##
==========================================
- Coverage 82.85% 82.84% -0.01%
==========================================
Files 1151 1151
Lines 455961 455880 -81
Branches 455961 455880 -81
==========================================
- Hits 377768 377691 -77
- Misses 55238 55247 +9
+ Partials 22955 22942 -13 ☔ View full report in Codecov by Harness. 🚀 New features to boost your workflow:
|

f58e128 to
372429f
Compare

d1d1d2f to
0267ad1
Compare

 gene-bordegaray
left a comment
gene-bordegaray
left a comment
There was a problem hiding this comment.
approved with some non blocking suggestoins. Thank you @xavlee
e7f8b42 to
0108b7c
Compare

|
Rereviewed after changes and everything looks good 👍 |

 NGA-TRAN
left a comment
NGA-TRAN
left a comment
There was a problem hiding this comment.
Looks great. It is a pleasure to review. Nice explanation.
I wonder if we should add an attribute in the explain to show this property? Maybe in a follow-up PR? If it is not that invasive or very easy to review, maybe adding that in this PR?
| /// | ||
| /// For example, with `GROUP BY (a, b)`, `Partial(vec![0])` means all rows | ||
| /// for each value of `a` are contiguous, while an `(a, b)` tuple may recur | ||
| /// within that range. |
There was a problem hiding this comment.
Does this mean I have 2 keys (a, b) and data is sorted on (a) only?
| assert_eq!( | ||
| aggregate.group_completion_mode, | ||
| GroupCompletionMode::Partial(vec![0]) | ||
| ); |
| // This captures the behavior before #24438. When the source can declare | ||
| // `(key, time_bin)` group-contiguous, the corresponding case can use | ||
| // `EmissionType::Incremental`. | ||
| assert_eq!(aggregate.cache().emission_type, EmissionType::Final); |
0108b7c to
6e369ce
Compare
2fae45d to
bb3dc16
Compare
bb3dc16 to
64a6e55
Compare
gene-bordegaray
left a comment
gene-bordegaray
left a comment
There was a problem hiding this comment.
this also looks good, just needs a rebase
3a0ecb6 to
1fd156e
Compare

 xudong963
left a comment
xudong963
left a comment
There was a problem hiding this comment.
Nit: finish updating the runtime documentation from “ordered” to “group-complete.”

## Which issue does this PR relate to?

- Part of apache#24438.

## Rationale for this change

A source can concatenate several sorted logical runs into one DataFusion
output partition. The resulting stream may be globally unsorted while
every distinct `(key, time_bin)` tuple still occupies one contiguous
range.

This PR records how aggregate planning handles that layout before
grouped input properties are available. It provides the behavioral
baseline for the remaining PRs in the stack.

## What changes are included in this PR?

- Add a single-partition `TestMemoryExec` fixture containing two sorted
logical runs whose `(key, time_bin)` order resets at the record-batch
boundary.
- Aggregate by the complete `(key, time_bin)` tuple and verify the
result.
- Assert that planning selects `InputOrderMode::Linear`,
`EmissionType::Final`, and `SingleHashAggregateStream`.

## Stack

1. [apache#24737 — test: cover unsorted contiguous groups in one
partition](apache#24737) ← **this
PR**
2. [apache#24697 — refactor: separate aggregate group completion from input
ordering](apache#24697)
3. [apache#24698 — feat: add grouped equivalence
properties](apache#24698)
4. [apache#24497 — feat: stream aggregates over grouped
input](apache#24497)

## Are these changes tested?

The new aggregate test executes the single-partition input and
snapshot-checks all four grouped sums.

## Are there any user-facing changes?

No.

## Review this layer

[View only this PR
layer](apache@36969e7)

|
What is the status of this PR? If it is ready to merge, perhaps we can resolve the conflicts and get the CI to pass |

|
@gene-bordegaray : Since Xavier is on vacation, I wonder whether you could help resolve conflicts and have CI passes so we can merge? |

|
Hi folks, I will rebase the PR and resolve the conflicts today. |
cca3e3f to
9402397
Compare
|
@alamb I resolved the conflicts and CI just passed so this guy should be ready to merge 🙇🏻 |
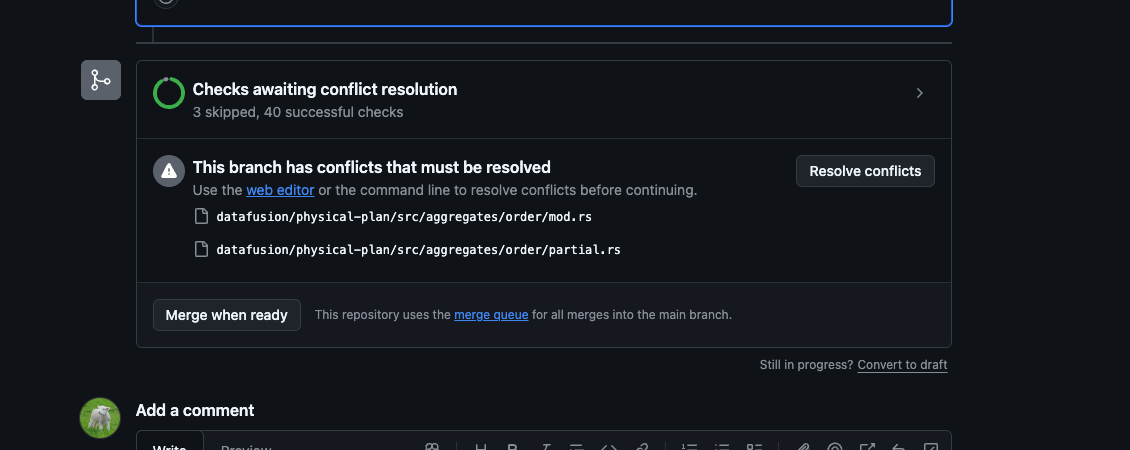
🤔 seems another conflict @xudong963 and @jayzhan211 shall we merge this? |
|
I'll address these shortly. It seems like renaming GroupOrdering -> GroupClustering is prone to quite a lot of conflicts 😅 |

9402397 to
2fd4763
Compare

|
Instead of a "sorted" property, we instead declare clustering - this means a |
Right, data is not sorted and thus I do not think |
|
clustering != sorted, so we cannot assume an input is sorted for SortPreservingMerge based on the clustering. Existing use cases of SortPreservingMerge remain unaffected since ordering metadata is preserved. Clarification- we could have an input that is clustered and sorted (sorting implies clustering), which would allow us to use SortPreservingMerge. |


|
Thanks all! |


## Which issue does this PR relate to?

- Part of apache#24438.
- Builds on apache#24737 and apache#24697, both merged.

## Rationale for this change

Aggregation can recognize completed groups when all rows with the same
grouping-key tuple occur in one contiguous run within a partition.
Sorted input provides this guarantee, and the runs can also appear in an
arbitrary order:

```text
AAABBBCCCC -> ordered and grouped
CCCAAABBB  -> grouped; each group can be completed when its run ends
AAABBBAACC -> A appears in separate runs
```

This PR represents that guarantee in `EquivalenceProperties`, allowing
execution-plan producers to declare grouping tuples and consumers to
check whether an input satisfies a grouping requirement.

## What changes are included in this PR?

### Semantics and propagation

A grouping assertion describes a complete expression tuple within every
output partition. `[a, b]` and `[b, a]` identify the same groups. The
guarantee applies to the complete pair; a guarantee for a subset such as
`[a]` requires its own proof.

Grouping assertions are correctness guarantees supplied by producers.
DataFusion trusts the asserted row layout. Producers can declare derived
tuples such as `[bhandle, date_bin(timestamp)]` directly.

- Store grouping tuples alongside ordering, equality, and constant
information in `EquivalenceProperties`.
- Normalize tuples using expression equivalences and constants, removing
duplicate expressions.
- Check grouping requirements against declared tuples and grouping
implied by lexicographical ordering prefixes.
- Project a tuple when every expression can be represented in the
output, including explicitly declared derived expressions.
- Remap grouping expressions during schema replacement.
- Preserve a declared grouping tuple through `UnionExec` when every
input satisfies it, explicitly or through ordering.
- Clear explicit grouping assertions at aggregation, sorting,
repartitioning, and partition-merging boundaries where execution can
invalidate them.

### Public API additions

- `GroupingEquivalenceClass` represents complete grouping tuples and
supports construction, insertion, lookup, clearing, schema rewriting,
iteration, and display.
- `EquivalenceProperties::{geq_class, normalized_geq_class,
add_grouping, add_groupings, clear_groupings, grouping_satisfy}` expose
grouping metadata and its analysis.
- `TestMemoryExec::try_with_grouping_information` attaches grouping
assertions in physical-plan tests and examples.

Execution-plan producers attach these assertions through the
`EquivalenceProperties` held by `PlanProperties`. The follow-up apache#24497
consumes them to derive `GroupClusteringMode::Full` for eligible
aggregates.

## Stack

1. [apache#24737 — test: cover unsorted contiguous groups in one
partition](apache#24737) (merged)
2. [apache#24697 — refactor: use group clustering terminology in aggregate
execution](apache#24697) (merged)
3. [apache#24698 — feat: add grouping equivalence
properties](apache#24698) ← **this
PR**
4. [apache#24497 — feat: stream aggregates over grouped
input](apache#24497)

## What is the testing strategy for this PR?

Tests cover complete-tuple semantics, equivalent permutations,
normalization through equivalences and constants, ordering-derived
grouping, complete and incomplete projection mappings, explicitly
declared derived expressions, operator boundaries, and UNION propagation
with selective tuple retention, mixed grouping/ordering proofs, schema
rewrites, and input permutations.

`aggregate_clears_explicit_grouping` covers partial and single
aggregation with reordered and aliased grouping keys. Both cases fail
without the aggregate boundary clear and pass with it.

Local validation passed the extended workspace suite, including 2,997
physical-plan tests and 546 SQL logic files, and all-target/all-feature
Clippy with warnings denied.

## Are there any user-facing changes?

Yes. The additive Rust APIs above let plan producers describe contiguous
grouping tuples and let consumers evaluate grouping requirements. The
streaming aggregate optimization follows in apache#24497.

## Review this layer

[View this PR's
diff](https://github.com/apache/datafusion/pull/24698/files)

Backport the Apache DataFusion apache#24438 stack onto DataDog branch-55:
- apache#24737: unsorted contiguous-group regression coverage
- apache#24697: group-clustering terminology and aggregate APIs
- apache#24698: grouping equivalence properties and propagation
- apache#24497: incremental aggregation over explicitly grouped input
- apache#26852: invalidate grouping assertions when clearing orderings

Adapt the changes to DF55's existing aggregate streams. Single-stage
clustered aggregation continues to use GroupedHashAggregateStream;
partial and final aggregation retain the existing specialized streams.
Do not import the unrelated DF56 aggregate-stream migration.

Include the constant-key, grouping-set, and PartialReduce guards. Extend
blocked-input tests across single/final and migrated/legacy execution,
and retain sort-option and metadata-invalidation coverage. Update DF55
plan snapshots, the wrapped memory-limit error assertion, and the API
upgrade guide.

Validation: 503 SQL test files passed, 3347 focused expression/plan unit
tests passed, and all-targets/all-features clippy passed. Extended tests
exposed a dictionary sort-fuzzer failure also reproduced on the unchanged
branch-55 base (root seed 1793724857; dataset 15872832093508421016; query
12465732596605393044; config 11717754459111916353).

Upstream-Commit: 59d74ca
Upstream-Commit: d93699c
Upstream-Commit: 320a7d2
Upstream-Commit: 64a5955
Upstream-Commit: 3c3898e
Upstream-Commit: 86f93b6
Co-authored-by: xavlee <52435309+xavlee@users.noreply.github.com>

…ache#24697)

Backport apache#24697

Adapt the clustering API and names to DF55's existing aggregate streams.
Include the public API guide and plan-display expectation updates.

Upstream-Commit: d93699c
DataFusion 56 renames OrderedFinalAggregateStream to
ClusteredFinalAggregateStream (apache/datafusion#24697), and the memory
consumer with it. The fair pool's exemption for that consumer and the spill
replay pool's final-aggregate check match it by name, so on DataFusion 56
neither matched anymore. Match the new name, and update the tests, docs and
comments that use the old one.


Which issue does this PR relate to?
Rationale for this change
Aggregate execution currently uses
InputOrderModeto select execution paths and recognize completed groups.A group can be completed incrementally when its rows form one contiguous run: once the run ends, that group cannot appear again in the same input partition. Sorted input supplies this guarantee, and unsorted input can supply it too:
This PR describes the input's clustering guarantee with
GroupClusteringModeand uses clustering terminology throughout the aggregate execution machinery. Aggregate construction derives the mode directly from the existing ordering analysis. The follow-up in #24497 will also derive it from grouped equivalence properties.What changes are included in this PR?
InputOrderModefield withGroupClusteringMode::{None, Partial, Full}:None: Groups have no apparent clustering guarantee.Partial(indices): rows are contiguous on a subset of grouping expressions; a change in that tuple completes all groups in the preceding run.Full: rows are contiguous on the complete grouping tuple; a change in that tuple completes the preceding group.GroupOrderingtracker and itsPartialandFullimplementations toGroupClustering,GroupClusteringPartial, andGroupClusteringFull.group_clustering_modein aggregate plans and document the public API migration in the DataFusion 56 upgrade guide.Stack
Are there any user-facing changes?
Yes. This PR changes public Rust APIs:
AggregateExec::input_order_mode()is replaced byAggregateExec::group_clustering_mode(), returning the publicGroupClusteringModeenum.AggregateExec::compute_propertiesaccepts&GroupClusteringModein place of&InputOrderMode.GroupOrdering,GroupOrderingPartial, andGroupOrderingFulltypes inaggregates::orderare renamed toGroupClustering,GroupClusteringPartial, andGroupClusteringFull.GroupClustering::try_newtakes&GroupClusteringMode;new_group_valuestakes&GroupClustering.Aggregate plan output uses
group_clustering_mode=Fullandgroup_clustering_mode=Partial(indices)in place ofordering_mode=Sortedandordering_mode=PartiallySorted(indices). SQL results and aggregate execution-path selection retain their existing behavior.Review this layer
View this PR's diff