Repository navigation
[Python] exitCode: <139> when csv file converting parquet using pandas/pyarrow libraries #32152
Description

Our main requirement is to read source file (structured/semi structured /unstructured) which are residing in AWS s3 through AWS redshift database, where our customer have direct access to analyze the data very quickly/seamlessly for reporting purpose without defining the schema info for the file.
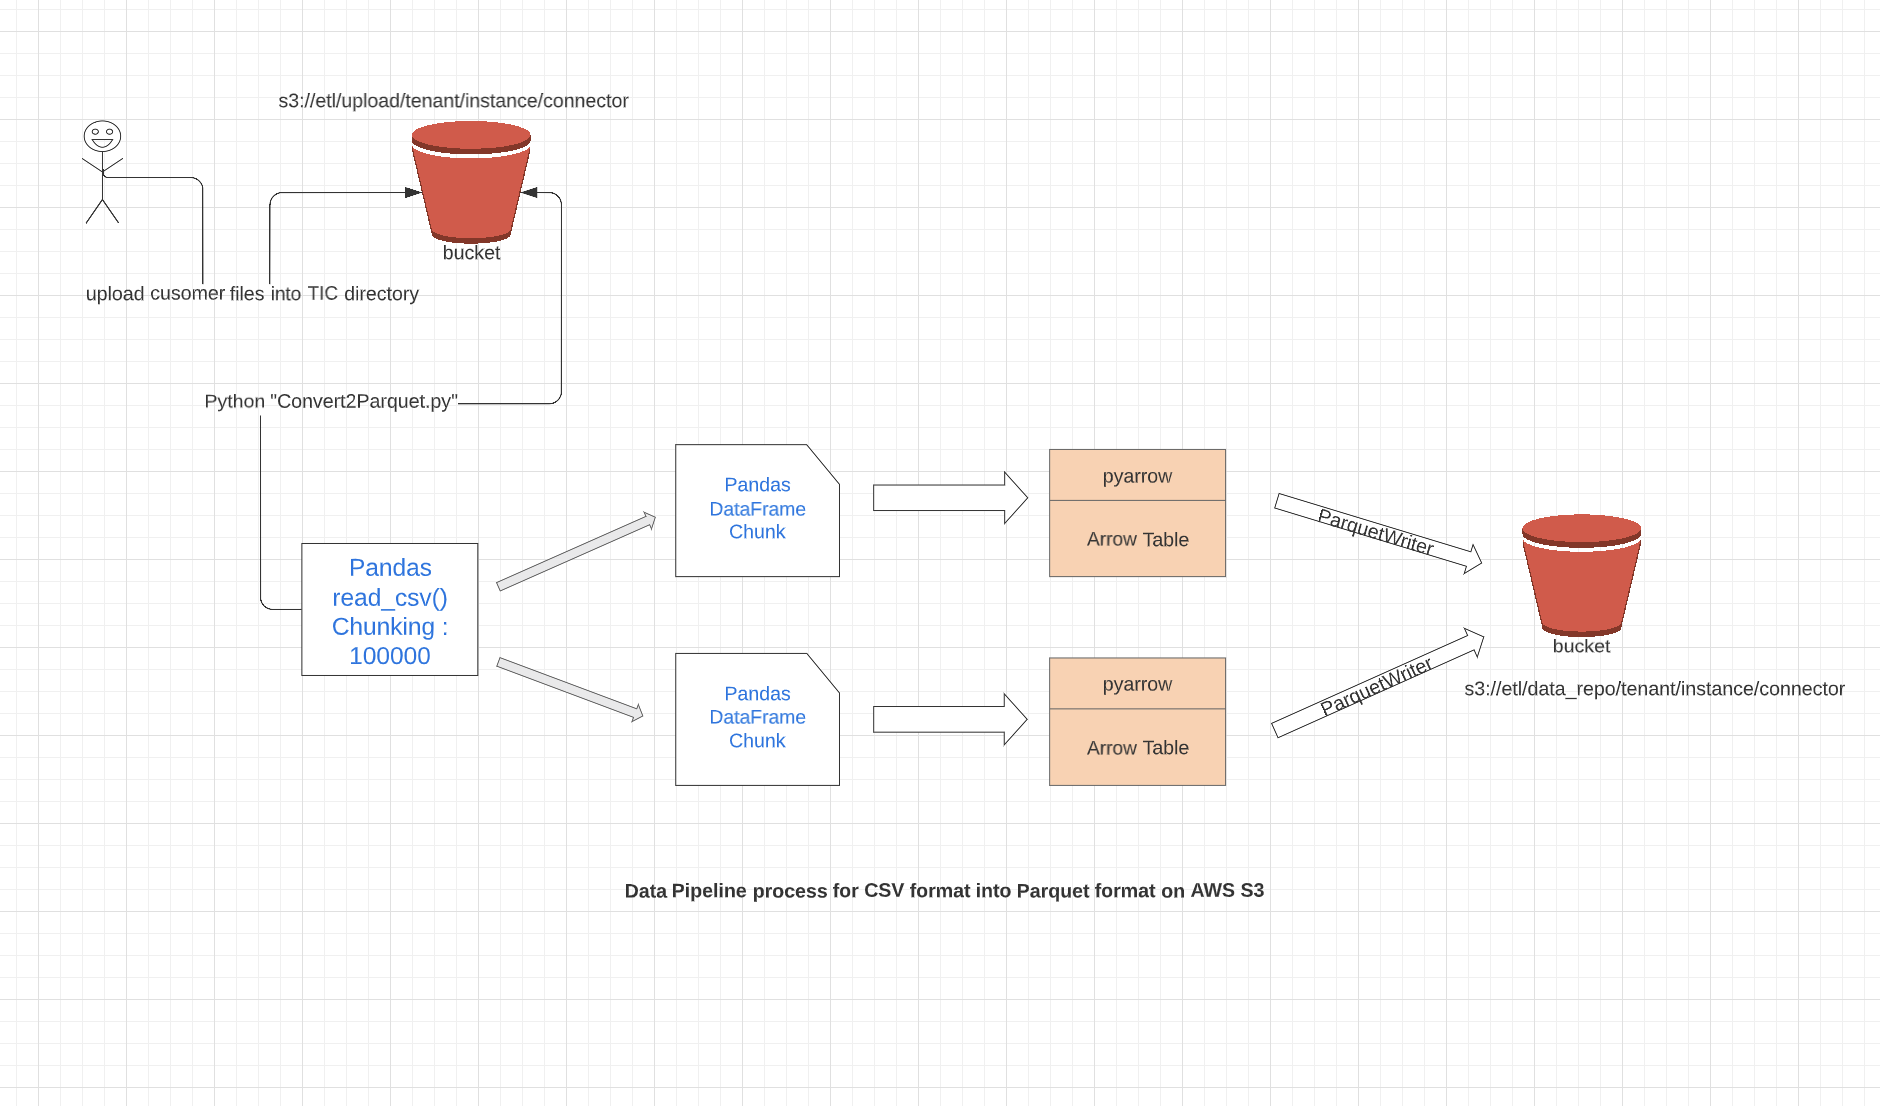
We have created an data lake (aws s3) workspace where our customers dumps csv/parquet huge size files (like 10/15 GB). We have developed a framework which is consuming pandas/pyarrow (parquet) libraries to read source files in chunking manner and identifying schema meaning (datatype/length) and push it to AWS Glue where AWS redshift database can talk seamlessly to s3 files can read very quickly.
Following is the snippet of parquet conversion where i'm getting this error. Please take a look
read_csv_args = {'filepath_or_buffer': src_object, 'chunksize': self.chunkSizeLimit, 'encoding': 'UTF-8','on_bad_lines': 'error','sep': fileDelimiter, 'low_memory': False, 'skip_blank_lines': True, 'memory_map': True} # 'verbose': True , In order to enable memory consumption logging
if srcPath.endswith('.gz'):
read_csv_args['compression'] = 'gzip'
if fileTextQualifier:
read_csv_args['quotechar'] = fileTextQualifier
with pd.read_csv(**read_csv_args) as reader:
for chunk_number, chunk in enumerate(reader, 1):
# To support shape-shifting for the incoming datafiles, need to make sure match file with number of columns if not delete
if glueMasterSchema is not None:
sessionSchema=copy.deepcopy(glueMasterSchema) #copying using deepcopy() method
chunk.columns = chunk.columns.str.lower() # modifying the column header of all columns to lowercase
fileSchema = list(chunk.columns)
for key in list(sessionSchema):
if key not in fileSchema:
del sessionSchema[key]
fields = []
for col,dtypes in sessionSchema.items():
fields.append(pa.field(col, dtypes))
glue_schema = pa.schema(fields)
# To identify the boolean datatype and convert back to STRING which was done during the BF schema
for cols in chunk.columns:
try:
if chunk[cols].dtype =='bool':
chunk[cols] = chunk[cols].astype('str')
if chunk[cols].dtype =='object':
chunk[cols] = chunk[cols].fillna('').astype('str').tolist()
except (ParserError,ValueError,TypeError):
pass
log.debug("chunk count", chunk_number, "chunk length", len(chunk), 'glue_schema', glue_schema, 'Wrote file', targetKey)
#log.debug("during pandas chunk data ", chunk,"df schemas:", chunk.dtypes)
table = pa.Table.from_pandas(chunk, schema=glue_schema , preserve_index=False)
log.info('Glue schema:',glue_schema,'for a [file:',targetKey|file:///',targetKey])
log.info('pandas memory utilization during chunk process: ', chunk.memory_usage().sum(), 'Bytes.','\n\n\n')
# Guess the schema of the CSV file from the first chunk
#if pq_writer is None:
if chunk_number == 1:
#parquet_schema = table.schema
# Open a Parquet file for writing
pq_writer = pq.ParquetWriter(targetKey, schema=glue_schema, compression='snappy') # In PyArrow we use, Snappy generally results in better performance
log.debug("table schema :", pprint.pformat(table.schema).replace('\n', ',').replace('\r', ','),' for:', inputFileName)
# writing the log information into s3://etl_activity
etlActivityLog.append({'tableObjectName': targetDirectory[:-1], 'sourceFileName': inputFileName, 'targetFileName': parquetFileName, 'message': 'File Converted Successfully', 'number of rows processed': str(table.num_rows), 'fileStatus': 'SUCCESS'})
logInfo = self.read_logInfo(etlActivityLog)
self.s3Handle.putObject(s3Client, 'etl_process_all.json', logInfo, bucketName, self.etlJobActivityLogFolder )
# Write CSV chunk to the parquet file
pq_writer.write_table(table)
i += 1
log.info( 'chunk count:', i, 'for a given [file:',targetKey,'whitelist:',targetDirectory[:-1|file:///',targetKey,'whitelist:',targetDirectory[:-1]])
# Close a Parquet file writer
if pq_writer is not None and pq_writer.is_open:
pq_writer.close()
pq_writer = None
s3key = outputDirectory + targetDirectory + parquetFileName
self.s3Handle.waitForFile(s3Client, bucketName, s3key)
log.info('Metadata info:', table.column_names, 'number of columns:', table.num_columns, 'number of rows:', table.num_rows, 'Glue Object Name:', targetDirectory[:-1])
log.debug('Wrote file', targetKey, 'with chunk count:', chunk_number)
log.debug('Stream copy', targetKey, 'to parquet took:', datetime.now() - start_time)
log.info('Final parquert convert:',sys.exc_info())
except (EOFError, IOError) as x:
log.error("error in source file for EOFError, IOError" % x)
raise SystemExit('convert2Parquet EOFError:'+sys.exc_info())
except (ValueError, ParserError) as x:
log.error("error in source for ValueError, ParserError" % x)
raise SystemExit('convert2Parquet valueError:'+sys.exc_info())
finally:
if pq_writer is not None and pq_writer.is_open:
pq_writer.close()
Reporter: Mahesha Subrahamanya
Original Issue Attachments:

Note: This issue was originally created as ARROW-16822. Please see the migration documentation for further details.
Activity
asfimport commentedon Jun 13, 2022
Mahesha Subrahamanya:
following versions have used to reproduce the issue so please suggest incase to upgrade to latest version of libraries have addressed this issue.
{}pandas{}{}==1.3.3; python_full_{}{}version{}>= "3.7.1" \{}pyarrow==5.0.0; python_full_{}{}version{}{} >= "3.6.2" and python_{}{}version{}{} < "3.10" and python_{}{}version{}>= "3.6"asfimport commentedon Jun 16, 2022
Weston Pace / @westonpace:
Can you raise a different error other than SystemExit or provide a traceback? This is a rather large snippet of code to parse through to figure out which line might be failing. Also, the exit code you are mentioning (139) does not seem like something that pyarrow would configure. Pyarrow doesn't really interact with exit codes.
asfimport commentedon Jun 16, 2022
Mahesha Subrahamanya:
asfimport commentedon Jun 16, 2022
Mahesha Subrahamanya:
we did try with traceback, exception handler however nothing worked here.
when pandas hand over the chunk data to pyarrow which is responsible to converting into parquet file. we suspect during the process of converting it's failing however it's not throwing the right error code/error message hence need your help. kindly let me know if anything can be helpful is really appreciated. since we are running into this issue we couldn't deliver this project as it's dependency at the python libraries like pandas/pyarrow.
thisisnic commentedon Oct 26, 2026
Closing as stale; if anyone has similar issues in a later arrow version, please open a new issue