


Persistent, local-first memory for AI agents. Engraphis stores scoped project knowledge, retrieves relevant evidence across vector, lexical, graph, and code search, and returns bounded context with sources an agent can inspect.
The local engine uses SQLite and works offline. It keeps changes over time instead of silently replacing facts, and grounded recall cites retrieved memories or abstains when evidence is weak.
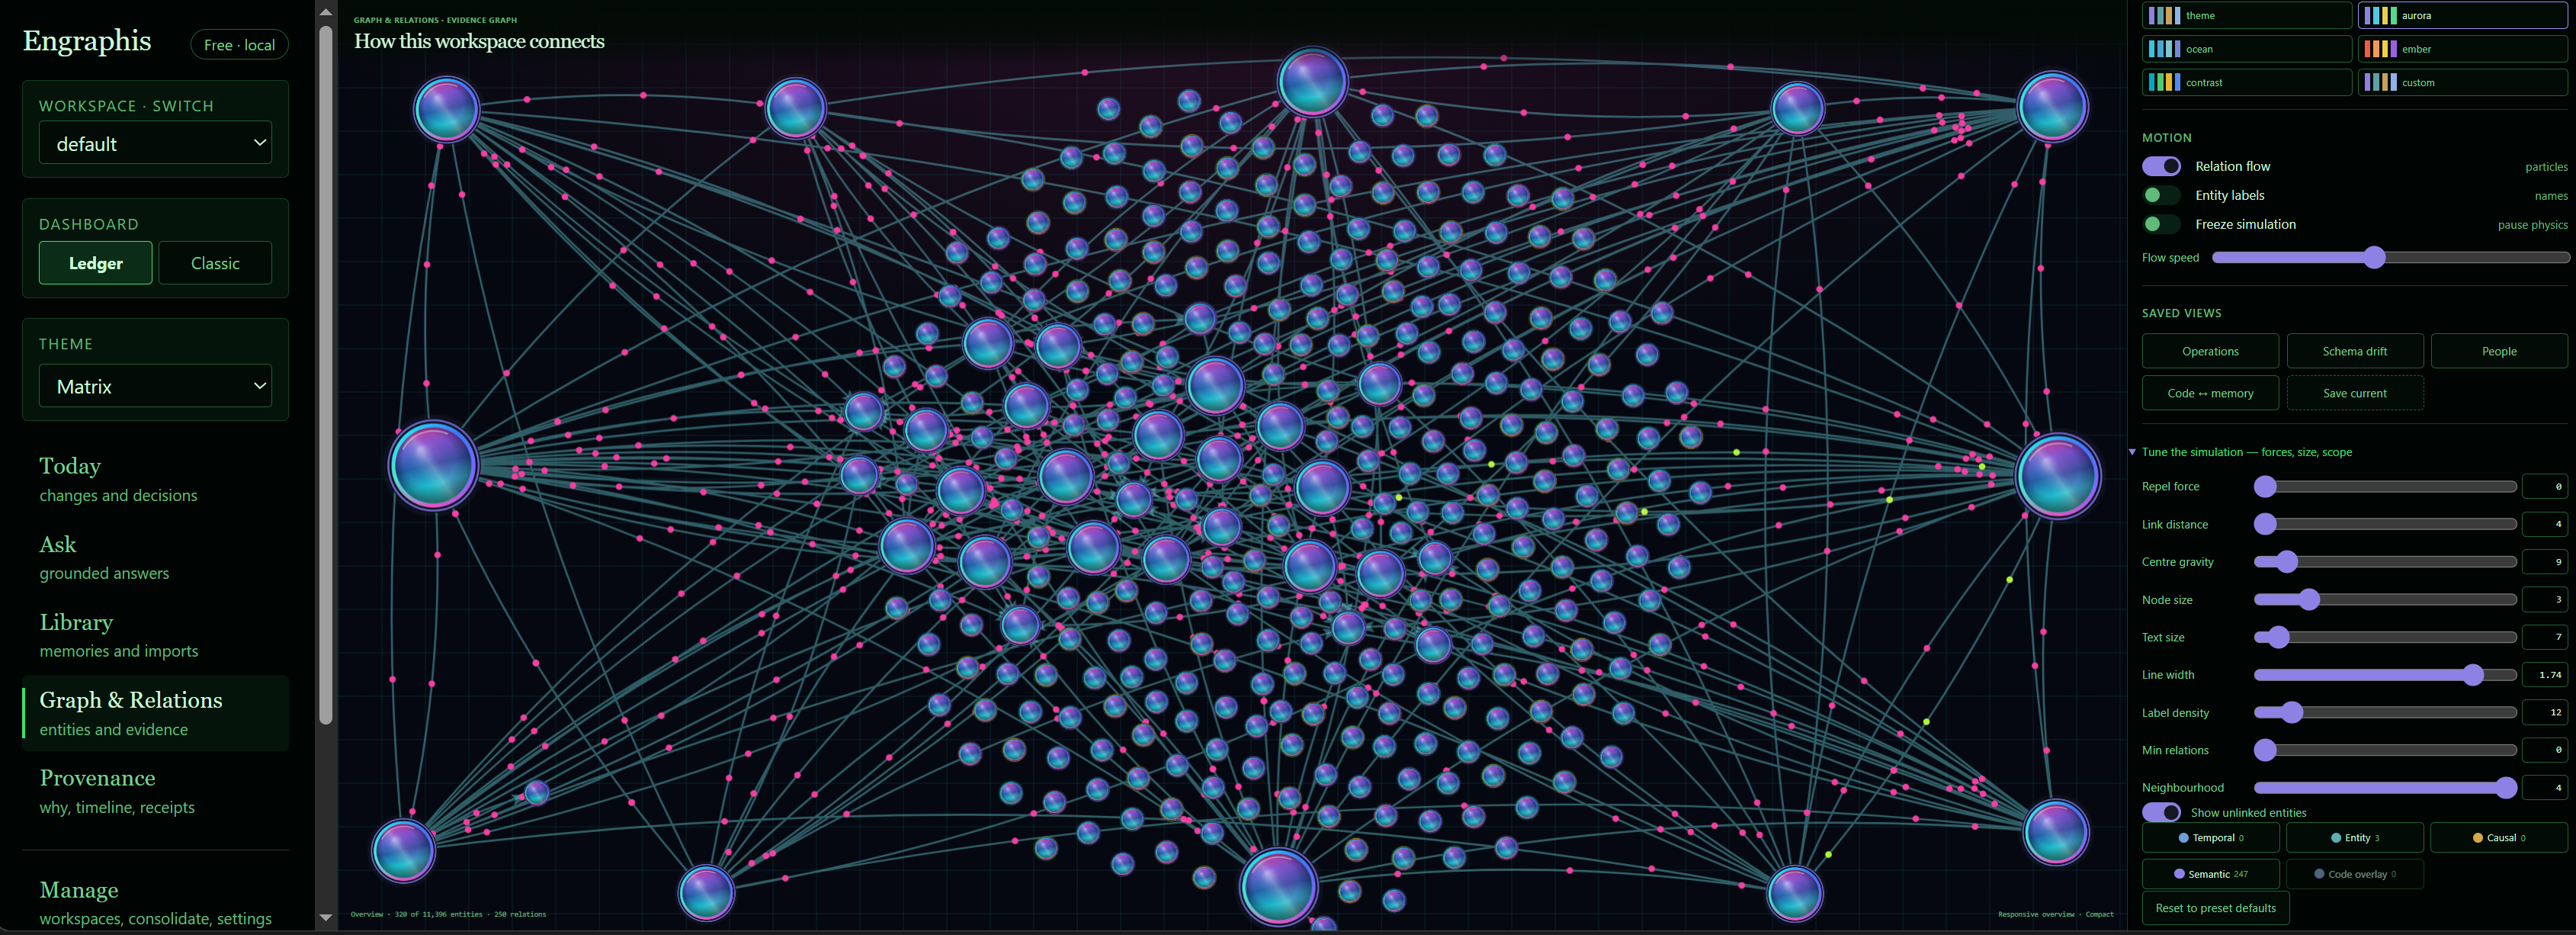
Explore memories and their relationships in the local dashboard.
The full local application requires Python 3.10 or newer. The NumPy-only core supports Python 3.9+.
python -m pip install "engraphis[all]"
engraphis-dashboard
The dashboard opens at http://127.0.0.1:8700. Local use needs no cloud account or API key.
To use the Python service directly:
from engraphis.service import MemoryService

memory = MemoryService.create("engraphis.db")
memory.remember("Auth migrated from JWT to PASETO.", workspace="acme", repo="api")
hit = memory.recall("Why did we change auth?", workspace="acme", repo="api")
print(hit["context"])
Connect a coding agent over MCP with the agent setup guide.
- Continuity: Organize memories by workspace, repository, and session, with a last-session handoff.
- Useful recall: Combine vector, lexical, graph, and code-aware retrieval, then pack results to a hard context budget.
- Grounded answers: Preserve provenance and temporal history; cite support or abstain when it is insufficient.
- Temporal history: Timeline can select known versions whose validity has ended before result limits. The dashboard uses
closed_only=trueonGET /api/timelinefor “Only superseded versions.” Closed history prioritizes lexical matches (the literal query and up to 32 expanded terms, using the final ranker's Unicode lowercasing) before scoring at most 500 eligible candidates; semantic-only matches outside that window can be omitted. SQLite may scan and sort more rows than this candidate cap. - Spec Studio: Inspect prompt specifications and scoped memory clusters with deterministic coverage, ambiguity, and conflict checks; review suggestions before changing memory.
- Operator control: Keep the core local and offline-capable, with explicit controls for hosted services and external LLM providers.
- Free Jev on paid plans: Pro and Team include managed Jev decisions up to 500 calls per person per day, with no personal provider key.
The current registered artifact contains three deterministic offline fixture runs. It separates context size, retrieval quality, and grounded decision checks; these small fixtures do not establish general task performance.
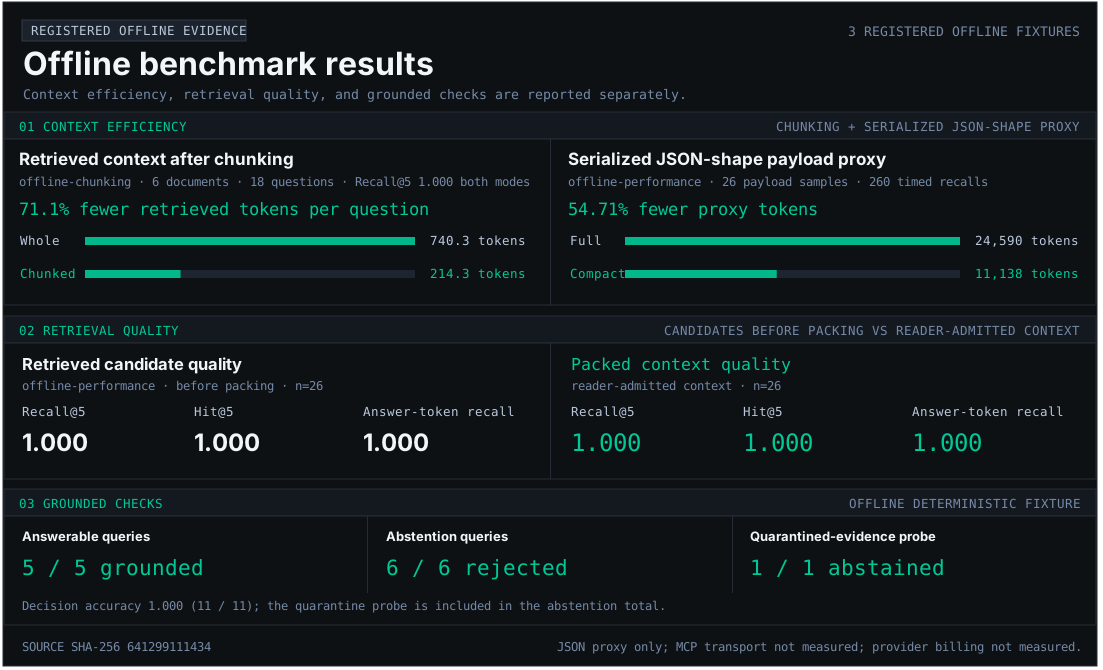
Three offline fixtures separate context reduction, candidate and packed retrieval quality, and grounded behavior. The chart shows the artifact checksum prefix; see the benchmark guide for the full checksum and reproduction steps.
| Fixture | Result | Quality check |
|---|---|---|
| Structure-aware chunking | Mean retrieved top-5 context: 740.3 → 214.3 tokens per question (71.1% lower, 18 questions) | Recall@5 = 1.000 in both modes |
| Recall payload proxy | JSON-shape proxy: 24,590 → 11,138 tokens (54.71% lower, 26 samples; 260 timed recalls) | Candidate and packed Recall@5, Hit@5, and answer-token recall are each 1.000 |
| Grounded decisions | 5/5 answerable queries grounded; 6/6 abstention queries rejected, including 1/1 quarantined-evidence check | 11/11 decisions correct |
The payload figure is a serialized JSON-shape estimate, not an MCP transport measurement or provider billing total. See the Benchmark methodology for artifact identity, counting methods, reproduction commands, external-evaluation boundaries, and limitations.
Jev is included free with every paid plan: Pro and Team. Every legitimate Pro user and each eligible Team named seat, including paid viewers, with an active paid, trial, or test entitlement receives managed Jev at no additional customer charge and without a personal provider key. Local advisory decisions stay free for everyone; BYOK, a personal TypeSafe key, is optional for non-paid or direct use and its provider charges may apply. Managed Jev is available for paid plans; the hosted control service enables it with its provider key.
Each paid individual receives up to 500 Jev calls per person per day, free. Usage is per person, not pooled across a Team and not monthly. Each evaluated call counts once, including a batched request; calls beyond the daily maximum are not served. Admitted attempts that fail or are interrupted remain counted, and no overage is charged. The account portal reports that member's remaining calls for the current day.
Use Review with Jev in the local dashboard for evidence-support and contradiction checks; the MCP decision tool covers command and completion reviews. Remote calls need per-call consent plus a public or internal classification, and Jev cannot write memories, change grounded-recall requirements, authorize commands, or certify completion.
Recall route selection is experimental and BYOK-only: engraphis_recall_context with allow_remote=true, or classic MCP with planning="auto" and jev_assisted=true. On 40 public synthetic tasks it changed no retrieval quality, so no retrieval-quality improvement is claimed.
See hosted plans and Jev details.
- Configuration reference
- MCP tool reference
- Agent and LLM provider setup
- Architecture and query planning
- Docker deployment
- Document import
- Cloud Sync
- Pi extension
- Spec Crawl and Spec Studio
- Memory write review
- Coding-agent file protection
- Security policy
- Hosted plans and licensing
Engraphis is licensed under Apache-2.0. The license does not grant trademark rights. See LICENSE, NOTICE, and the licensing guide. The hosted control plane and managed services are private services.